Thirteen projects from Modern Software Concepts in Python
(JHU EP 605.256, Summer 2026) — from web scraping to a fine-tuned,
deployed language model. Every block below is rendered from
projects.json by the Flask app itself.
Filter
ONE DATASET, ELEVEN PROJECTS
96,948
admission records scraped & cleaned
2,081
universities represented
5,154
distinct programs normalized
11
of the 13 projects built on this data
A 4.0 is no better than a 3.0.
Acceptance rate by GPA across the 45,475
results that report both a GPA in this band and a decided
outcome. Every point falls between 48.5% and 55.0%, and the trend
runs slightly down rather than up — which is why my admissions
model leans on program and degree, not grades.
Computed from cleaned_gradcafe.json by
build_stats.py · self-reported data,
decided outcomes only
01
M01
Personal Portfolio Website
Cloud & DevOpsMay 2026
A personal portfolio site built with Flask from scratch — application-factory pattern, blueprint-based routing, Jinja template inheritance, and an external stylesheet. The site you are reading right now, rebuilt at the end of the course as the final project portfolio.
Learned How to structure a Flask application properly from day one — factories, blueprints, and template inheritance — instead of one big script.
Private repo
HomeProjects
02
M02
Web Scraping — Grad Café Applicant Data
Data EngineeringMay 2026
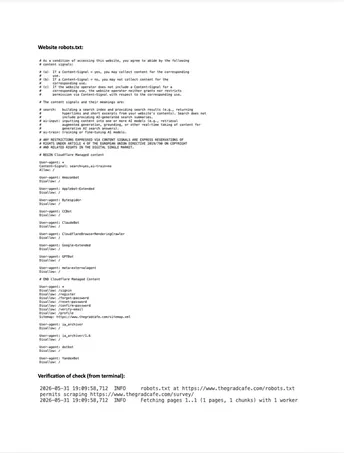
A robots.txt-compliant scraper that collects ~100,000 graduate-admissions results from thegradcafe.com using a hybrid urllib + headless-Selenium + BeautifulSoup workflow, then parses, validates, and deduplicates them into a clean JSON dataset.
Learned That real-world scraping is mostly engineering around the messiness — JavaScript-rendered pages, explicit waits, field validation, and reproducibility — not the parsing itself.
Private repo
robots.txt Check
03
M03
Databases — PostgreSQL + GradScope Dashboard
Data EngineeringJun 2026
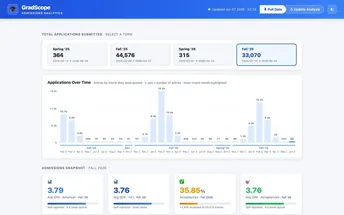
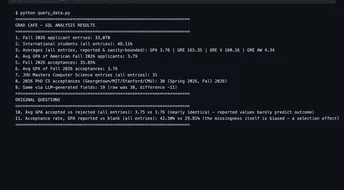
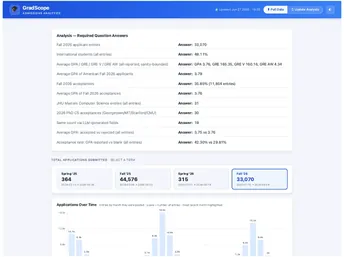
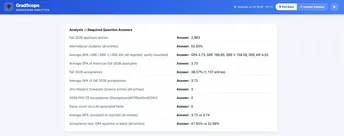
Loads the Module 2 Grad Café dataset into PostgreSQL, answers a set of analysis questions in SQL, and serves the results on a dynamic Flask dashboard ("GradScope") with Pull Data and Update Analysis actions guarded by concurrency control.
Learned How to design idempotent data loads and guard shared state — the busy-lock pattern that keeps a scrape and a recompute from stepping on each other.
Private repo
DashboardConsole Output
04
M04
Testing & Documentation
Cloud & DevOpsJun 2026
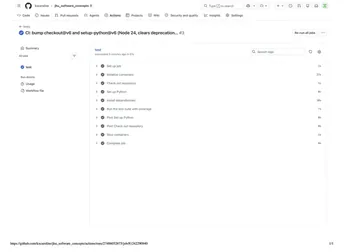
Makes the Grad Café analytics service test-driven and documented without changing its behavior: a pytest suite at 100% coverage organized with markers, run in GitHub Actions against a real PostgreSQL service, plus Sphinx documentation published to Read the Docs.
Learned That 100% coverage is less about the number and more about the discipline — every branch I had to reach taught me something about my own design.
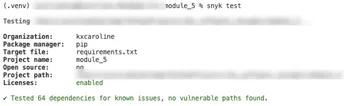
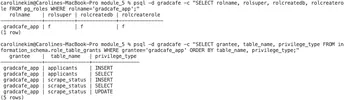
Hardens the existing service to a software-assurance standard: 10.00/10 Pylint with errors resolved rather than silenced, injection-safe parameterized SQL via psycopg composition, a least-privilege database role, a dependency graph, reproducible packaging, and a Snyk supply-chain scan — all enforced in CI.
Learned How to think like an attacker about my own queries, and why least-privilege access is cheap insurance you set up once and benefit from forever.
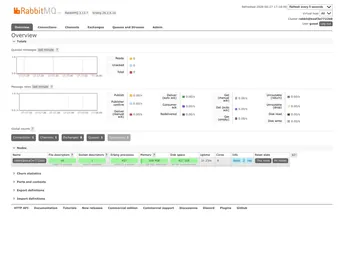
Refactors the service into containerized microservices — Flask web tier, RabbitMQ broker, background worker, PostgreSQL, and an optional LLM inference service — where button clicks publish tasks and return 202 immediately, and the whole stack runs reproducibly with one compose command.
Learned The value of decoupling: once the web tier stopped doing long-running work itself, deployment, scaling, and failure-handling all got simpler at once.
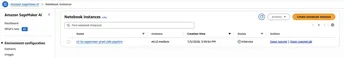
Two AWS workflows: a boto3 pipeline that pulls the Grad Café dataset from a private S3 bucket into a SageMaker notebook, and the full Module 6 microservice stack deployed to an EC2 instance with Docker Compose using published images.
Learned How the pieces of a real cloud deployment fit together — IAM, security groups, and credentials management turned out to matter as much as the code.
Private repo
EC2 AppNotebookS3 Bucket
08
M08
Data Preparation & Statistics
Data EngineeringJul 2026
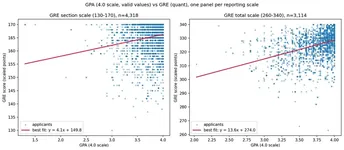
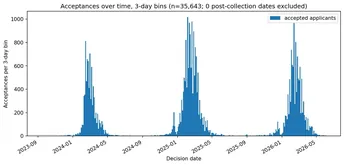
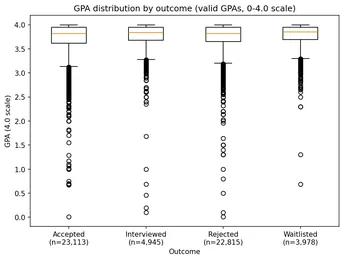
A cleaning and exploratory-analysis workflow over the ~100k-row Grad Café dataset: every cleaning rule records what it dropped or coerced in an audit ledger (99,941 → 96,948 rows), followed by SciPy statistics, Matplotlib visualizations, and a cleaned write-back to S3.
Learned To make data cleaning auditable — a ledger of every dropped row changed how much I trust (and can defend) the downstream analysis.
Private repo
GPA vs GREOver TimeBy Outcome
09
M09
K-Means Clustering of Program Names
ML & ModelingJul 2026
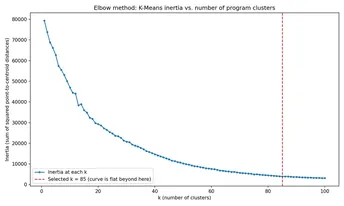
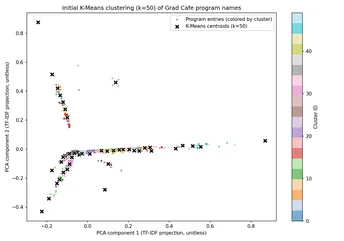
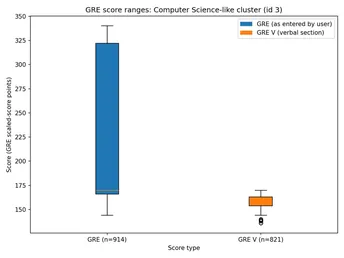
Groups 5,861 messy, differently-entered graduate program names ("Business and Economics" vs "Business Economics") into a smaller set of coherent program areas using TF-IDF vectorization, PCA dimensionality reduction, and K-Means clustering.
Learned How much of applied ML is representation: the clustering only became meaningful once the text vectorization and dimensionality were right.
Private repo
Elbow CurveFirst ClustersCS Cluster
10
M10
Immuno-Oncology Clinical-Trial Pipeline
ML & ModelingJul 2026
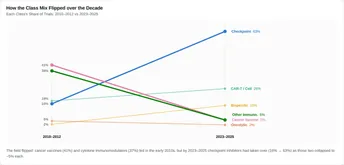
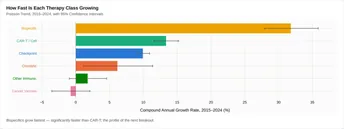
A reproducible pipeline over the ClinicalTrials.gov registry answering where immuno-oncology development is concentrating: 10,971 trials tagged into six therapy classes by a controlled-vocabulary classifier validated against three human labelers, with publication-style figures, an interactive dashboard, and an inferential-statistics layer.
Learned How to take a research question end-to-end — classifier validation against human labels and a leakage-clean re-audit taught me what it takes for an analysis to hold up to scrutiny.
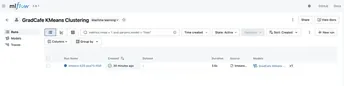
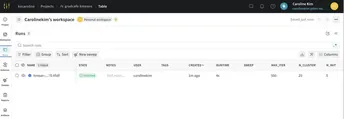
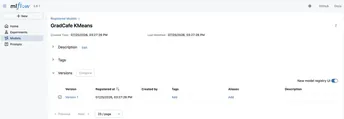
Wraps the Module 9 clustering pipeline with experiment tracking so every training run's parameters, inertia metric, and fitted model are recorded and comparable — MLflow as the required tracker, Weights & Biases as the optional second one.
Learned Why serious ML work is impossible without tracking: once runs became comparable artifacts instead of terminal scrollback, iteration got dramatically faster.
Private repo
Cluster RunW&B RunModel Card
12
M12
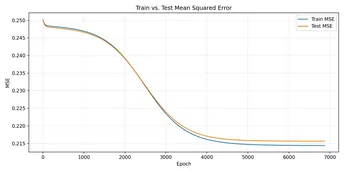
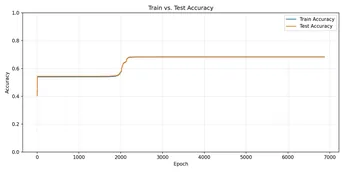
Neural Network from Scratch
ML & ModelingAug 2026
A two-layer neural network implemented in NumPy only — no framework — that predicts graduate-admission outcomes from GPA, GRE, and program features, with leak-free preprocessing (training-set medians and standardization) and early stopping with best-epoch restore.
Learned What backpropagation actually does — writing the gradients by hand demystified every framework I will ever use on top of them.
Private repo
MSE CurveAccuracy Curve
13
M13
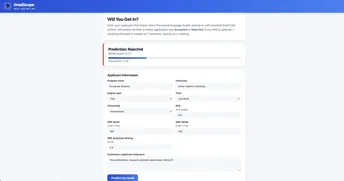
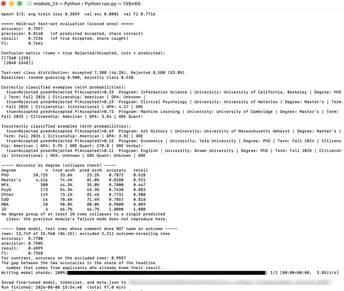
LM Fine-Tuning & Deployment — "Will You Get In?"
ML & ModelingAug 2026
Fine-tunes DistilBERT for binary admissions prediction on the Grad Café dataset and deploys it as the interactive "Will You Get In?" page of a Flask app — a single shared applicant-to-text template guarantees training and serving stay consistent.
Learned The training/serving-skew problem first-hand — and how one shared serialization module, imported by both sides, eliminates a whole class of silent bugs.
Degree type moves this more than grades do: doctoral admit rates here are far lower, so a 3.9-GPA PhD applicant scores below a 3.4-GPA master's with no GRE. The model reads the base rate, not the record.